To reduce Claude API costs, find what one completed task costs, change one setting at a time, and judge each change by cost per task. This guide is for a CFO whose Claude usage bill keeps climbing. It covers where Anthropic reports cost by workspace, API key and user, what usually drives a rising bill, and which setting to test for each driver. It matters because a total bill that rises with usage cannot tell you whether the app got cheaper per task or just got busier.
Enterprise AI integration connects an AI model, such as Claude, to the systems your company already runs. U.S.-based senior engineers at The Gnar Company build those connections. Gnar is a Claude Select Services Partner in Anthropic’s Claude Partner Network.
Anthropic's cost optimization cookbook describes its own method as "applying the Claude API's cost levers one at a time". The prices below are Anthropic's list prices as of November 2026. Anthropic's Usage and Cost Analytics API reports both the cost at list prices and the cost after discounts.
Why does a Claude API bill climb faster than the plan?#
As general advice, check six causes when a Claude API bill climbs. They are more tasks, resent conversation history, long answers and thinking, tool definitions on every call, cache misses, and a model or effort level that costs more than the task needs.
The first cause is growth in usage. The other five are about what each task sends and gets back. Anthropic bills each of those as tokens. Its pricing page says "Billing is based on actual monthly usage".
Agent loops make the growth inside one task steep. Anthropic's guide to optimizing for cost and intelligence says "by default every turn of an agentic task resends the entire growing conversation: system prompt, tool definitions, and every prior turn". It gives the effect: "A 40-turn task sends its first turn 40 times, so task cost grows with roughly the square of turn count".
Output is the other heavy line. The same guide says "Output tokens cost five times input tokens on Claude Haiku 5.5, Claude Sonnet 5.5, Claude Opus 5.5, Claude Fable 5.2, and Claude Fable 5.1". As of November 2026, the pricing page lists Claude Opus 5.5 at $4 per million input tokens and $20 per million output tokens.
Finding which of the six caused the rise takes a breakdown, which is the next step.
Where can you see Claude API costs by workspace, API key and user?#
Anthropic reports Claude API usage and cost in the Claude Console and through its Usage and Cost Analytics API. The API breaks the bill down by model, workspace and API key, and can also group it by the user or service account behind each request. For one request, the response itself carries the token counts.
Anthropic's Usage and Cost Analytics API page says it reports usage and cost "broken down by the dimensions you choose, such as model, workspace, API key, or the user or service account behind each request". It lists two endpoints. One reports token counts and request counts. The other reports cost in USD.
| Where | What it breaks down | What to know |
|---|---|---|
| Console Usage and Cost pages | Usage and cost for a Claude Console organization | The API page says its data is similar to what these pages show |
| Usage and Cost Analytics API | Model, workspace, API key, actor, service tier and more | In beta, and needs an Admin API credential on a Console organization |
| The usage object in each response | Uncached input, cache writes, cache reads and output for one request | Your own app logs it, so you can add a task id |
The Analytics API page also says "The Admin API isn’t available to organizations on the claude.ai Team plan or to individual Claude Console accounts". Claude Enterprise organizations use a key with the read:analytics scope instead.
Two lines on that page matter for a finance team. The cost endpoint returns "amount (the cost after discounts and before any credits are applied)" and "list_amount (the cost at list prices)". And recent data moves. The page says "Data typically refreshes within 4 hours of the underlying usage and can take up to 24 hours". It adds that values "can be revised as late events arrive and reconciliation runs, until about 7 days after the end of the calendar month".
Close a month's numbers only once 7 days have passed after it ends. The page itself says "for final totals, query only months that ended at least 7 days ago".
The API can also show which API keys spend the most. The page lists "Find top consumers" as a use, ranking results "to answer questions such as “which API keys spend the most this month?”" Anthropic's workspaces page adds that you can "Track usage and costs by workspace" through the same API.
What if the climbing bill is Claude Code?#
Claude Code spend shows up in different places depending on how your company pays for it. Anthropic's Claude Code costs page says "On Teams and Enterprise plans, usage draws from each member’s seat allowance. On the Console and on cloud providers, usage is billed per token to your organization".
| How you pay | Where you see spend | Per-user numbers |
|---|---|---|
| Claude for Teams or Enterprise | Spend report in org analytics | Spend report CSV; Enterprise Analytics API on Enterprise |
| Claude Console (API) | Console Cost page | Console dashboard, Claude Code Analytics API |
| Amazon Bedrock, Google Cloud’s Agent Platform or Microsoft Foundry | Your cloud billing console | OpenTelemetry or an LLM gateway |
On Teams and Enterprise, the costs page says the spend report "covers usage-credit spend and appears once usage credits are turned on". On the three clouds in the last row, it says "the analytics dashboards and the Claude Code Analytics API do not cover this usage".
On Amazon Bedrock, the costs page says Claude Code is billed per token to your cloud account. Amazon's AWS Budgets guide describes a monthly cost budget "to track all costs associated with your account". It says "You can choose to be alerted for both actual (after accruing) and forecasted (before accruing) spends".
How do you work out the cost of one task?#
Price each request's token counts at the model's list rates, then add up every request that belongs to one task. Anthropic's guide gives the method under "How to price a task". It says to "Price each of the five token counts in a response’s usage at its own rate". The five are uncached input, 5 minute cache writes, 1 hour cache writes, cache reads and output. The guide adds "When the advisor tool or compaction is enabled, some tokens are reported only in usage.iterations and not in the top-level totals. Sum over usage.iterations instead, and price advisor_message entries at the advisor model’s rates." Server tools add charges on top of tokens. The pricing page says "Web search is available on the Claude API for $10 USD per 1,000 searches, plus standard token costs for search-generated content."
The guide then says to "Sum them across the task’s requests". A task here is one unit of work your business cares about. It could be one closed support ticket, one processed order or one summarized contract.
As general advice, these steps get you there:
- Give each app its own workspace or API key, so its spend can be read on its own.
- Have the app log the usage object of every request with a task id.
- Price each token count at its own list rate for the model.
- Add up the requests for each task.
- Divide by the number of completed tasks.
The last step matters. A failed attempt still bills its tokens. Anthropic's cookbook says "a cheaper model that takes more turns or retries can cost more end to end". Dividing by completed tasks puts that failure cost where it belongs.
Here is an illustrative task, not a client. Assume an agent answers one order question in a few requests on Claude Opus 5.5. Across those requests, the task uses 10,000 uncached input tokens, 4,000 tokens of 5 minute cache writes, 60,000 cache read tokens and 3,000 output tokens. The rates are Anthropic's list prices for Claude Opus 5.5 as of November 2026.
| Token count | Arithmetic | Cost |
|---|---|---|
| Uncached input | 10,000 x $4 per million tokens | $0.040 |
| 5 minute cache writes | 4,000 x $5 per million tokens | $0.020 |
| Cache reads | 60,000 x $0.20 per million tokens | $0.012 |
| Output | 3,000 x $20 per million tokens | $0.060 |
| Total for one task | $0.040 + $0.020 + $0.012 + $0.060 | $0.132 |
Output is under 4 percent of this task's tokens (3,000 of 77,000), but it is the largest single cost line. That is the five to one price gap at work.
Should you judge a change by the total bill or by cost per task?#
Judge each change by cost per completed task, read next to its pass rate. The total bill answers a budget question. It cannot answer whether a change worked, because it also rises when more tasks run. Anthropic's guide says "Compare on cost per completed task, not per token" when choosing or switching models.
Anthropic's cookbook explains the unit: "We measure cost per task instead of cost per token because a model with a higher sticker price can be the cheaper option if it finishes the job in fewer turns". It pairs that with a quality bar. "Pass rate allows us to establish a quality bar such that we don't degrade the quality of the agent itself as we reduce cost per task".
Here is the illustrative task again over two months. In month two, assume one change: the prompt asks for a shorter answer, and output falls from 3,000 to 2,000 tokens per task. Assume the pass rate is the same in both months. To keep the arithmetic short, the example holds input counts fixed. Volume grows from 20,000 completed tasks to 30,000.
| Line | Month one | Month two |
|---|---|---|
| Completed tasks | 20,000 | 30,000 |
| Cost per completed task | $0.132 | $0.112 ($0.132 minus 1,000 x $20 per million) |
| Total bill | 20,000 x $0.132 = $2,640 | 30,000 x $0.112 = $3,360 |
The total rose by $720 (about 27 percent). Cost per task fell by $0.020 (about 15 percent). Read alone, the total makes the change look like a failure. As general advice, report both lines every month, with the pass rate beside cost per task.
Which setting should you test for each cost driver?#
Match what the usage data shows to one driver, and test the one setting that answers it. As general advice, the table maps each signal to the setting Anthropic's pages describe for it. The sections after it give each setting with its source and its limits.
| What the usage data shows | Likely driver | Setting to test first |
|---|---|---|
| Input per task grows with the number of turns | Conversation history resent each turn | Compaction |
| Output is the largest cost line | Long answers or heavy thinking | A shorter answer shape for long answers, lower effort for heavy thinking |
| Input is high even on the first call | Tool definitions and a long system prompt | Tool search with deferred loading |
| Cache reads are a small share of input | Something breaks the cached prefix | Move changing text after the stable prefix |
| Simple, high volume tasks on a large model | Model choice | Claude Haiku 5.5 on the same task sample |
| Many requests no one waits on | Interactive pricing for work that can wait | The Batch API |
Anthropic's cookbook gives an order for these levers. It runs "Prompt caching", "Input token management", "Agent-loop efficiency", "Output token management", "Batch API" and then "Model selection and effort". It says model selection is "the easiest lever to pull but directly constrains the intelligence of your product".
Anthropic's guide to optimizing for cost and intelligence sorts the same levers by what they cost in quality. It opens with the tradeoff: "The most capable model can be too expensive at scale, and the least expensive model can fall short on quality". Its next point is "Prompt caching, token hygiene, batch processing, and a prompt audit against your current model all lower what you pay without lowering output quality". It adds that "batch processing trades latency for its discount".
How does conversation history drive up input tokens?#
Conversation history drives up input tokens because each new turn resends everything before it. A long chat or agent task pays again for its early turns on every later request. Prompt caching makes those resent tokens cheaper, and compaction makes the history shorter. They solve different parts of the problem.
Anthropic's compaction overview describes the second fix. "Compaction replaces the older turns of a conversation with a summary that Claude writes on the server, so you need no summarization code of your own". It says compaction "keeps a long conversation or agent task inside the context window, and it keeps the active context small, because response quality degrades as a conversation grows".
Context editing is a narrower tool. Anthropic's guide says "Context editing clears stale tool results". Its measurements came with a caution. The guide says context editing "cost more than it saved on the short run measured in this section and changed nothing on the long one". It also says "If you use context editing, clear in a few large batches, because each clear costs a cache write".
The guide's rule for all of these is "The context levers only pay on a session long enough to need them". As general advice, test compaction on your longest tasks first. Judge it by cost per completed task, which counts every token type, where input tokens are only one of them.
One model has a hard line. The guide says "With Claude Haiku 5.5 on the Messages API, compact a long conversation between tasks, before its prompt passes 100,000 tokens. Past that, every token of the request costs 5 times as much, output included".
Why Claude Code usage climbs in a long session#
Claude Code has its own version of this problem. The costs page says "Claude Code sends your full conversation with every request". It adds that "a one-line question in a session that has been open all day still draws usage for the whole conversation".
The page names other causes too. "Cache misses: your first message after a break longer than the cache lifetime misses the cache and reprocesses your full context". And "every subagent, and every agent a dynamic workflow spawns, sends its own requests on top of the main conversation’s". It notes that "When you want a fresh start instead of continuity, /clear costs nothing".
On a Pro, Max, Ultra, Team or Enterprise plan, the page says to run /usage. "Its breakdown recommends a change for behaviors behind 10% or more of your recent usage".
Why do output tokens and thinking tokens weigh so much?#
Output tokens weigh heavily because they cost five times input on Claude Haiku 5.5, Claude Sonnet 5.5, Claude Opus 5.5 and Claude Fable 5.2. Thinking counts as output, and in an agent loop, output also returns as input on later turns. Anthropic's guide says "every token the model writes comes back as input on every later turn, so you pay for a long answer again and again".
Thinking is billed even when you do not see it. Anthropic's page on steering thinking lists "Tokens Claude uses while thinking (billed as output tokens)". It says "You are billed for the full thinking process, not the thinking content visible in the response".
Anthropic's steering thinking page says to "lower the effort level before reaching for prompt-based steering". Anthropic's guide says "The effort parameter governs how much thinking, tool calling, and self-verification the model does". It adds that on the Messages API, "high is the default on most models, and medium on Claude Opus 5.5 and Claude Haiku 5.5". The thinking page says "To get less thinking on Claude Sonnet 5.5 and Claude Haiku 5.5, lower the effort level".
Effort has a quality cost that depends on the task. The guide says "how much accuracy it gives up depends on the task". Its instruction is to "Sweep two or three effort levels on a sample of your own traffic, each in a separate session". The reason it gives is that "changing top-level effort mid-session invalidates the cache and distorts the comparison".
The guide also describes a policy for tasks you can check. "When a task’s outcome is checkable, the cheapest policy on the effort curve is not a fixed setting: run every task at a low setting and re-run only the failures at a higher one". As general advice, test that policy against one fixed effort level on the same sample, and compare cost per completed task.
What max_tokens and structured outputs do to the bill#
Lowering max_tokens is not a way to get shorter answers, and structured outputs add a little input. Anthropic's guide says "max_tokens caps a single response, invisibly to the model, so lowering it does not make the model economize". It adds "The turns that needed the room are discarded and still billed".
For shorter answers, Anthropic's cookbook says "if you just want the visible response to be shorter, prompt Claude for it. Specify the exact output shape in the prompt, ideally with an example". On an earlier model, Anthropic ran a small bug triage agent with three answer formats. The guide reports that the answer formats "differ in what you pay far more than in what they get right".
Structured outputs control the format of an answer, and they add a little input. Anthropic's structured outputs page says "Claude automatically receives an additional system prompt explaining the expected output format". It says "Your input token count is slightly higher". It also says "Changing the output_config.format parameter invalidates any prompt cache for that conversation thread".
How do tool definitions and MCP servers add to every call?#
Every tool definition loaded into a request is sent as input tokens on every API call, whether Claude uses the tool or not. MCP servers can add many tools at once. Anthropic's guide says "Every tool definition attached to a request is input on every turn, and a few MCP servers add up to hundreds of them".
The pricing page lists where tool tokens come from. One source is "The tools parameter in API requests (tool names, descriptions, and schemas)". It also says "the API also automatically includes a special system prompt for the model that enables tool use". For Claude Opus 5.5 and Claude Sonnet 5.5, it lists that system prompt at 286 tokens with tool choice auto or none.
Anthropic's tool search page puts a size on it. A typical setup with GitHub, Slack, Sentry, Grafana and Splunk servers "can consume ~55k tokens in definitions before Claude does any work". It says "Tool search typically reduces this by over 85 percent". Tool search loads only the tools a request needs.
Here is an illustrative line, not a client. On Claude Opus 5.5, those ~55k tokens of definitions cost 55,000 x $4 per million tokens = $0.22 per call when sent uncached. Read from cache, they cost 55,000 x $0.20 per million tokens = $0.011 per call.
Tool search has limits. The same page says standard tool calling "is a better fit when you have fewer than 10 tools, every tool is used in every request, or your tool definitions are small (less than 100 tokens total)". It also says the tool definitions that search loads "count as input tokens like any other tool definition".
Claude Code handles this differently. Its costs page says "MCP tool definitions are deferred by default, so only tool names and server instructions enter context until Claude uses a specific tool". It also says "Run /mcp to see configured servers and disable any you’re not actively using".
What stops prompt caching from saving money?#
Prompt caching stops saving money when the start of each request changes, so the cache is written again instead of read. A timestamp in the system prompt, a reordered tool list or an effort change can each do it. Anthropic's guide says "The cache is a byte-exact prefix match over the request in order (tools, then system prompt, then messages), so a change anywhere invalidates everything after it".
Anthropic gives a number to check against. The guide says "Over a full day of real traffic, agent loops read a median 84% of their input from the cache". It adds "Below about 80%, look for something breaking the cache". Our illustrative task reads 60,000 of its 74,000 input tokens from cache, about 81 percent.
A miss is expensive because a write costs more than a read. The guide says "A miss on either duration bills the whole prefix at the write price instead of the read price". On Claude Opus 5.5 and Claude Sonnet 5.5, it says a 5 minute cache write "costs 25 times a read".
A hit is where the saving comes from. As of November 2026, the pricing page lists a cache hit on Claude Opus 5.5 at "0.05x" the base input price, which is $0.20 per million tokens against $4 per million tokens for uncached input. By that arithmetic, a token read from cache costs 95 percent less than the same token sent uncached.
The common fix is about order. The guide says "Put nothing that changes per request, such as a timestamp or a queue position, ahead of the stable prefix: it turns every request into a full cache write". Anthropic's article on reducing cost with Claude Platform adds that "Claude Console provides prompt cache diagnostics, including reasoning for prompt cache misses".
As general advice, check the cache read share after every change you make. Many of the settings in this guide touch the prefix. The guide gives examples of changes that invalidate the cache, "such as a change to effort, the thinking configuration, the speed setting, the system prompt, or a tool definition".
When does a cheaper model or the Batch API reduce Claude API costs?#
A cheaper model reduces cost when its cost per completed task is lower at the same pass rate. The Batch API reduces cost when no one is waiting for the answer. Both need a test on your own cases first, because per token price is not cost per completed task.
On model routing, Anthropic's guide gives different starting models for different work. For "High-volume work with outputs you can check", it says "Try Claude Haiku 5.5 first". For most agent work, it says "start with Claude Opus 5.5 at its default effort (medium)". It explains that "A more capable model can finish a task with less work, which can offset much of the per-token premium". Its advice for the other direction is "Measure what a more expensive model buys on your own workload".
As of November 2026, the pricing page lists Claude Haiku 5.5 at $0.10 per million input tokens for prompts up to 100,000 tokens, and Claude Sonnet 5.5 at $2 per million input tokens.
Prompts written for older models can cost money on newer models. The guide says "Audit prompts against the model you run now, and again whenever you change models". It says a newer model follows old instructions "to the letter, producing extra tool rounds and extra writing that you pay for with no gain in accuracy". Anthropic's article on reducing cost lists stale few-shot examples among prompting patterns that "can inadvertently increase costs".
For the Batch API, Anthropic's guide says "Route every request no one is waiting on through the Batch API, and keep the interactive path for the rest". It says "The Batch API takes 50% off every token of a request, including cached ones, in exchange for results arriving any time within 24 hours". Its examples of unattended agent work are "evaluation runs, backfills, and scheduled jobs". The guide says "Batching combines with most of this page, but not with fast mode, message threads, or Claude Managed Agents sessions".
How do you test one change at a time, and what stops a runaway month?#
Test one change at a time against a fixed sample of real tasks, with a pass check for each task. Record cost per task and pass rate before and after. Keep a spend limit in place while you test, so a bad change cannot run up the bill all month.
Anthropic's guide gives the first step of its method. "Pull a few tasks from production logs, weighted like real traffic, and write outcome checks for each: tests pass, ticket closed, row count correct. Record cost per task beside the score". The cookbook sets the rule for reading the result. "Decide the pass rate you need from baseline runs, then treat it as the constraint and cost as the thing you minimize".
As general advice, run the loop like this:
- Measure cost per completed task and pass rate on the sample, with nothing changed.
- Pick the largest cost line from the usage data and the one setting the table above pairs with it.
- Change only that setting, and rerun the same sample.
- Keep the change only if cost per completed task fell and the pass rate held.
- Check the cache read share, then move to the next line.
One change per run is what makes the result readable. The cookbook says "Without an eval you cannot tell savings from regressions". It also points to a tool for this loop. In Claude Code, "Run /claude-api cost-optimize to profile where your spend goes and propose these levers one change at a time".
Spend limits are the backstop. Anthropic's guide says "A workspace spend limit is the backstop for both kinds of lever". The workspaces page says you can "set custom spend and rate limits for each workspace to protect against overuse". It also says "Workspace limits can keep a workspace below your organization’s limits, but they can’t raise those limits". Where Anthropic bills your organization directly, the same page says you can set email alerts at a spending amount you choose.
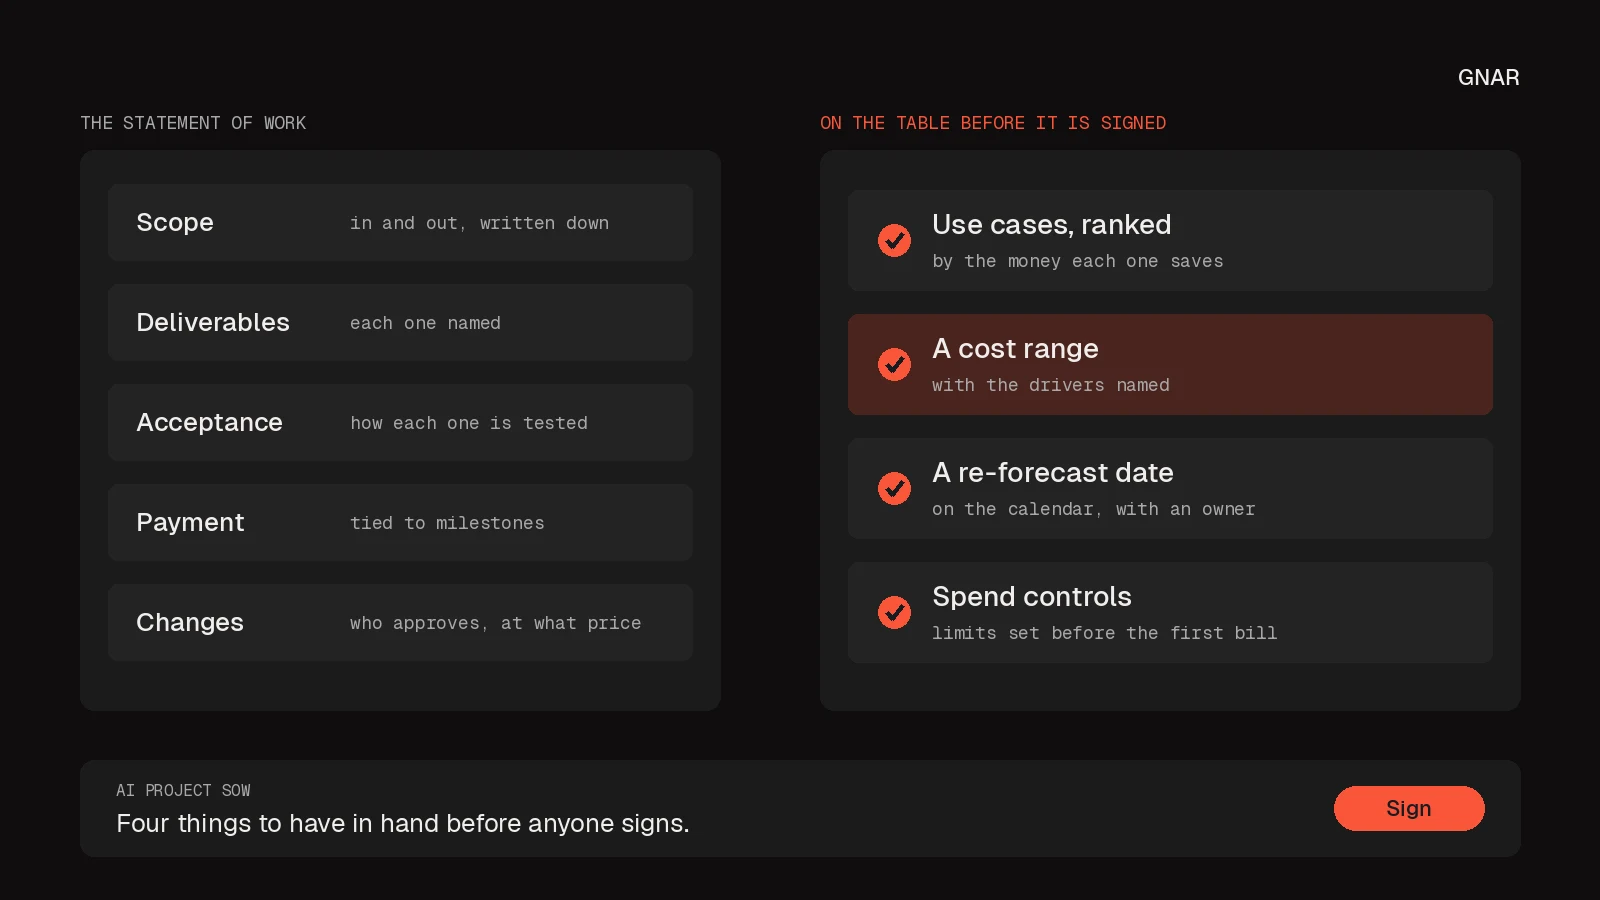
Know what a cap does before you set one. On the Start, Build and Scale usage tiers, a monthly spend cap applies. Anthropic's rate limits page says "Once you reach your tier’s spend cap, API usage pauses until 00:00 UTC on the first day of the next month, unless you request a higher limit sooner". Gnar's guide to what to have before signing an AI project SOW covers which limits to set, who is alerted and who may raise a limit.
What does The Gnar Company build for a company on Claude?#
Gnar's enterprise AI integration page says "Your AI can’t see your orders, customers or files, so people paste them into a chat by hand. We connect it to the systems where they already live". It adds "You choose what it can see and change, and every lookup and change is recorded."
The same page says "Most connections are small programs called MCP servers. Each lets AI use one system, only in the ways you allow". The page also says "Your connections are not tied to one model, so the next one uses the same connectors and rules".
The first step is Gnar Discovery and Design. The integration page says "Start with Gnar Discovery and Design, from two weeks and $15,000. You leave with a build plan that has a fixed price on it".
If your own team has the capacity and the direction, you do not need us. The method above uses Anthropic's public pages and your own usage data.