VGGT#
https://github.com/facebookresearch/vggt
While drafting my Repo Roundup post this week, I was intrigued by the VGGT project that came out of Facebook Research. Rather than review a few projects, I wanted to spend some time diving deeper into this one to understand it better. It is very much still in research project mode, but as a relative layperson in this area, I think I can see where it's headed from a practical use perspective.
What is it?#
This project is demo code from an award-winning paper titled "VGGT: Visual Geometry Grounded Transformer." It essentially takes one or many images (or video) of a subject and reconstructs it as a 3D scene. Behind the scenes, it uses a neural network to predict cameras, point maps, depth maps, etc., as opposed to more simplistic solutions that more or less attempt to stitch scenes together or actual 3d scanning hardware. It is capable of doing these calculations in less than a second, so very close to real-time.
What does VGGT predict?#
The README says the model directly infers extrinsic and intrinsic camera parameters, point maps, depth maps, and 3D point tracks. It does this from "one, a few, or hundreds of its views." The post says VGGT "takes one or many images (or video) of a subject and reconstructs it as a 3D scene."
The README's Detailed Usage example shows each output in turn.
| Output | What the README says |
|---|---|
| Camera parameters | The code comment reads "Extrinsic and intrinsic matrices, following OpenCV convention (camera from world)". |
| Depth maps | The example returns depth_map and depth_conf together. |
| Point maps | The example returns point_map and point_conf together. |
| 3D points from depth maps and cameras | The comment says this "usually leads to more accurate 3D points than point map branch". |
| 3D point tracks | The comment reads "choose your own points to track, with shape (N, 2) for one scene". |
The paper adds three details about the inputs and outputs.
- "The order of the images in the input sequence is arbitrary, except that the first image is chosen as the reference frame."
- The 3D points "are defined in the coordinate system of the first camera."
- The paper assumes the camera's "principal point is at the image center."
The README also says you can "optionally choose which attributes (branches) to predict."
Which award did the VGGT paper win?#
The post says VGGT is "demo code from an award-winning paper," and links the word "award-winning" to CVPR. CVPR's awards page, announced in Nashville on 13 June 2025, lists the paper as "CVPR 2025 Best Paper: VGGT: Visual Geometry Grounded Transformer."
| Detail | What the source says |
|---|---|
| Authors | CVPR lists Jianyuan Wang, Minghao Chen, Nikita Karaev, Andrea Vedaldi, Christian Rupprecht and David Novotny. |
| Affiliations | The README credits the "Visual Geometry Group, University of Oxford" and "Meta AI". |
| First posted | arXiv shows version 1 submitted on Fri, 14 Mar 2025. |
| README note | Its June 13, 2025 update says "Honored to receive the Best Paper Award at CVPR 2025!" |
CVPR's page also describes the paper as "a feed-forward neural network that can directly estimate all key 3D scene properties for hundreds of input views".
How many images does VGGT take, and how fast is it?#
The README says VGGT works from "one, a few, or hundreds of its views," and the paper's table shows time rising with the count. With 336 x 518 images on one NVIDIA H100 GPU, 1 frame takes 0.04 seconds and 200 frames take 8.75 seconds. In the paper's table, times stay under one second through 20 frames, and 50 frames take 1.04 seconds.
The post says VGGT works "in less than a second, so very close to real-time." The README says it takes "one, a few, or hundreds of its views."
The paper's Table 9 measures the feature backbone only. It used flash attention v3 and images with "a resolution of 336 x 518."
| Input frames | Time in seconds (one H100, 336 x 518 images) | Peak GPU memory in GB (one H100, 336 x 518 images) |
|---|---|---|
| 1 | 0.04 | 1.88 |
| 2 | 0.05 | 2.07 |
| 4 | 0.07 | 2.45 |
| 8 | 0.11 | 3.23 |
| 10 | 0.14 | 3.63 |
| 20 | 0.31 | 5.58 |
| 50 | 1.04 | 11.41 |
| 100 | 3.12 | 21.15 |
| 200 | 8.75 | 40.63 |
On one H100, the paper says the camera head is "lightweight, typically accounting for approximately 5% of the runtime and about 2% of the GPU memory used by the feature backbone."
The README's May 15, 2026 update says "With the same GPU memory budget, VGGT can now run on roughly 2-3x more input frames!" The paper's table, first posted on arXiv on 14 March 2025, predates that update.
The Gradio demo also takes video. In demo_gradio.py, its steps say "Videos will be automatically split into individual frames (one frame per second)." The README warns that "visualizing 3D points may take tens of seconds due to third-party rendering, independent of VGGT's processing time."
The paper's Limitations section says "several limitations remain." It lists three.
- "the current model does not support fisheye or panoramic images"
- "reconstruction performance drops under conditions involving extreme input rotations"
- "although our model handles scenes with minor non-rigid motions, it fails in scenarios involving substantial non-rigid deformation"
Why is this important?#
Previously, if you wanted to create a 3D model of something, you would need to use a 3D scanner (like a Leica BLK360) or something like the LiDAR scanner on an iPhone. While this method works well and can produce excellent results, the high-end hardware is expensive and the process is time-consuming. While there is still work to be done with VGGT, it is just a matter of time until we will be able to generate real 3D models on consumer-grade hardware using just 2D input sources in real-time!
Practical Uses#
Anywhere 3D models are needed, this could be applied. I would wager we'll see this or similar technology introduced on our mobile phones within 12-24 months. Other practical applications of this type of technology could be found in:
- 3D reconstruction and mapping
- Computer vision tasks
- AR/VR from 2D images
- Autonomous systems
- Content creation & media
- Photogrammetry and surveying
Can you use VGGT commercially?#
Only the VGGT-1B-Commercial checkpoint is licensed for commercial usage, as read on November 15, 2026. The README says "only the newly released checkpoint VGGT-1B-Commercial is licensed for commercial usage" and that "the original checkpoint remains non-commercial." LICENSE.txt grants "a non-exclusive, worldwide, non-transferable and royalty-free limited license."
The post says "Anywhere 3D models are needed, this could be applied."
| Piece | What the source says |
|---|---|
| Code | The README's July 29, 2025 update says "All code in this repository is now under a commercial-use-friendly license." |
| License change | The same update says the license now permits "commercial use (excluding military applications)". |
| Original checkpoint | The Hugging Face card for facebook/VGGT-1B lists the license as "cc-by-nc-4.0". |
| Commercial checkpoint | The README says "Access to the checkpoint requires completing an application form". It also says "The new checkpoint delivers similar performance to the original model." |
| Terms file | LICENSE.txt is titled "VGGT License" and says "v1 Last Updated: July 29, 2025". |
| Sharing it | LICENSE.txt says "You shall also provide a copy of this Agreement to such third party." |
| Research papers | LICENSE.txt says "you must acknowledge the use of Research Materials in your publication." |
| Prohibited uses | Its Acceptable Use Policy lists "Military, warfare, nuclear industries or applications, espionage" among others. |
| Support | LICENSE.txt says "Meta is under no obligation to provide any support services for the Research Materials." |
The README points to the full terms: "See the LICENSE file for details about the license under which this code is made available."
Demo#
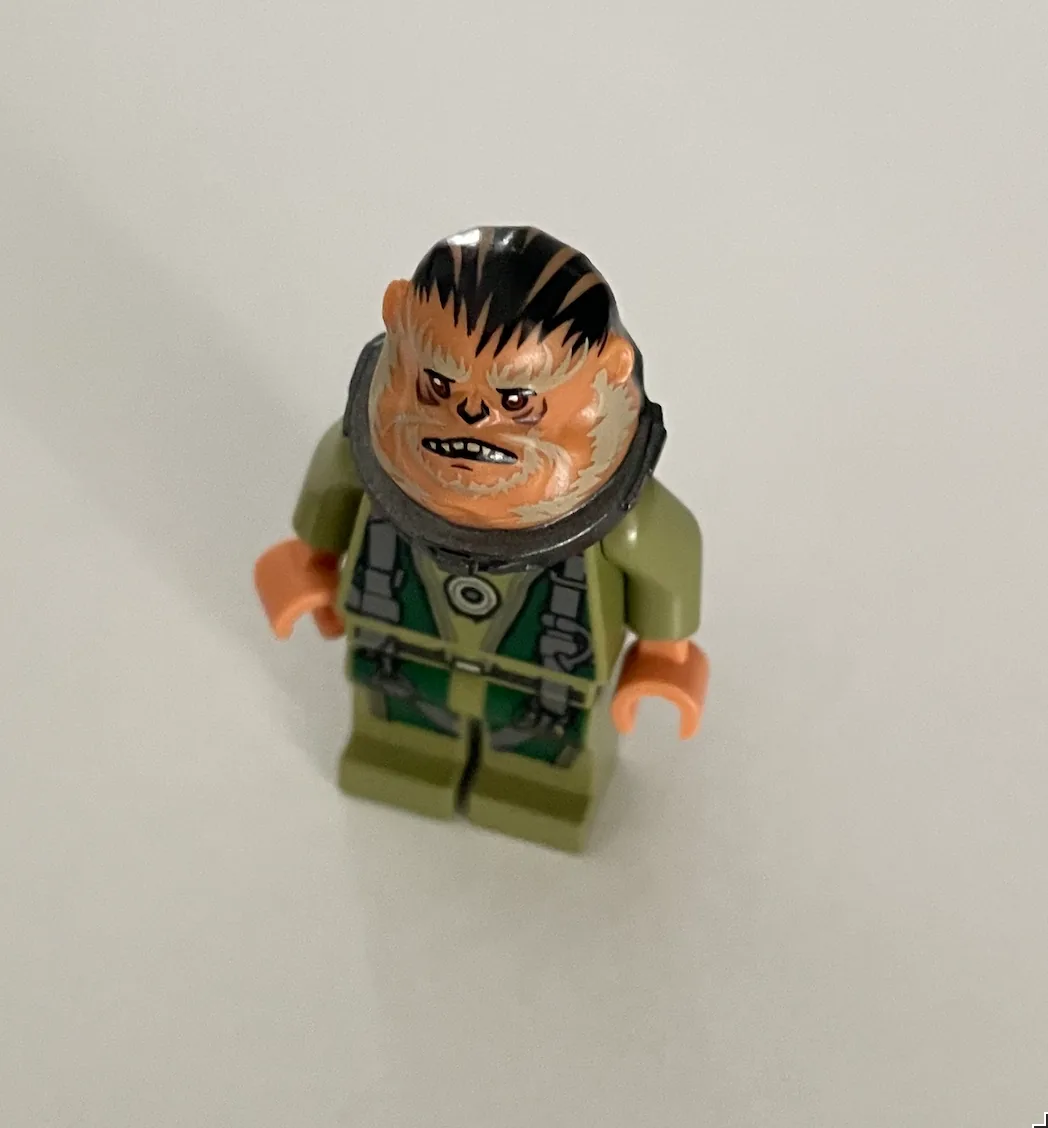
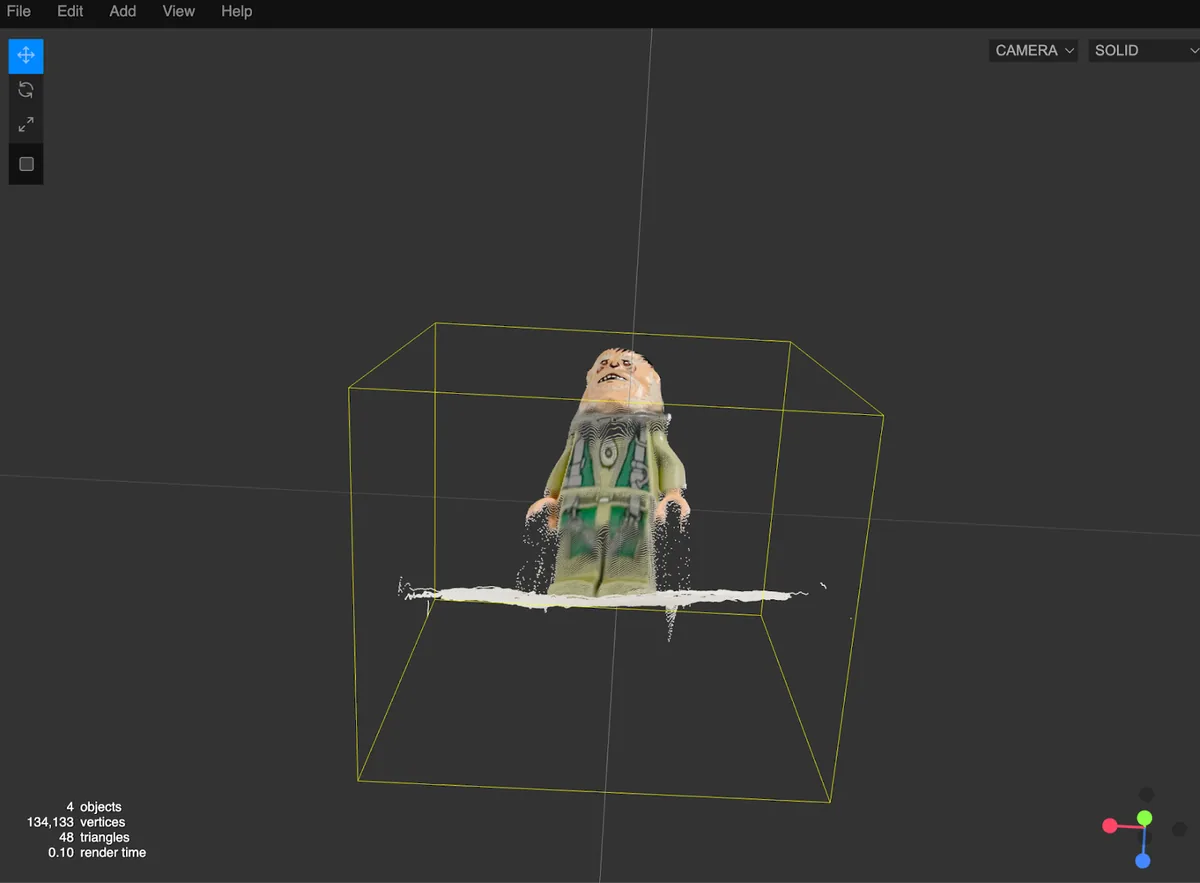
I tested it using just a single photo I took of a LEGO figurine that was near my desk. While the 3D model still has a number of artifacts, I think with either additional images or some post-processing, it would generate a relatively good 3D model. It outputs the results as a glb file that I imported into the Threejs sandbox.
Input Image:
Output Model: (a glb file I loaded in the threejs sandbox)
How do you run VGGT on your own photos?#
To run VGGT on your own photos, clone the repository, install the requirements, then start the Gradio demo and upload your images. The post says "I tested it using just a single photo I took of a LEGO figurine that was near my desk." The demo needs a CUDA GPU, because demo_gradio.py raises "CUDA is not available. Check your environment." when PyTorch cannot find one.
The README's Quick Start gives the first three commands.
git clone [email protected]:facebookresearch/vggt.git
cd vggt
pip install -r requirements.txt
For the demo, the README then says to run pip install -r requirements_demo.txt and python demo_gradio.py. The repository pins these versions, as read on November 15, 2026.
| Requirement | What the repository says |
|---|---|
| Python | pyproject.toml sets requires-python to ">= 3.10". |
| Core packages | requirements.txt pins torch==2.3.1, torchvision==0.18.1 and numpy==1.26.1. |
| Other packages | requirements.txt lists Pillow, huggingface_hub, einops and safetensors without versions. |
| Demo packages | requirements_demo.txt pins gradio==5.17.1 and viser==0.2.23. |
| Weights | The README's example says "This will automatically download the model weights the first time it's run, which may take a while." |
The demo's own on-screen steps are short.
- Upload Your Data. Use the Upload Video or Upload Images buttons on the left "to provide your input."
- Preview. "Your uploaded images will appear in the gallery on the left."
- Reconstruct. Click the Reconstruct button "to start the 3D reconstruction process."
- Visualize. "You can rotate, pan, and zoom to explore the model, and download the GLB file."
- Adjust Visualization (Optional). "After reconstruction, you can fine-tune the visualization using the options below".
The demo lists five controls under that optional step.
- Confidence Threshold. "Adjust the filtering of points based on confidence."
- Show Points from Frame. "Select specific frames to display in the point cloud."
- Show Camera. "Toggle the display of estimated camera positions."
- Filter Sky / Filter Black Background. "Remove sky or black-background points."
- Select a Prediction Mode. The demo says "Choose between" Depthmap and Camera Branch or Pointmap Branch.
The README says the model "shows surprisingly good performance on single-view reconstruction, although it was never trained for this task." That is the case the post tested with one photo.
It also says that if certain pixels "are unwanted (e.g., reflective surfaces, sky, or water), you can simply mask them by setting the corresponding pixel values to 0 or 1."
The README says you can "try the model with just a few lines of code" through VGGT.from_pretrained with facebook/VGGT-1B. It also says "Alternatively, you can install VGGT as a package." The package page says "you need to install PyTorch and torchvision" first, because "We don't list these as dependencies to avoid CUDA version mismatches."
What files can VGGT export?#
The Gradio demo lets you "download the GLB file," and the README says VGGT supports "exporting VGGT's predictions directly to COLMAP format." The post says "It outputs the results as a glb file that I imported into the Threejs sandbox."
| Format | What the source says |
|---|---|
| glb | In demo_gradio.py, the viewer steps say you can "download the GLB file". The script writes the scene to a file ending in .glb. |
| COLMAP | Run python demo_ |
| COLMAP with bundle adjustment | Add --use_ |
| COLMAP with reduced parameters | Add --max_ |
| Gaussian splatting | The README says "The exported COLMAP files can be directly used with gsplat for Gaussian Splatting training" and "we recommend gsplat==1.3.0". |
The README says to store the input images in /YOUR/SCENE_DIR/images/ and that "This folder should contain only the images." The result "will be automatically saved under /YOUR/SCENE_DIR/sparse/ in the COLMAP format," as cameras.bin, images.bin and points3D.bin.
The COLMAP script needs extra packages. A comment in requirements_demo.txt says "feel free to skip the dependencies below if you do not need demo_colmap.py," then lists pycolmap==3.10.0 and pyceres==2.3.
Can you train or fine-tune VGGT yourself?#
Yes. The README's July 6, 2025 update says "Training code is now available in the training folder, including an example to finetune VGGT on a custom dataset." The post says "It is very much still in research project mode."
| Resource | What the source says |
|---|---|
| Evaluation code | The README's May 3, 2025 update says "Evaluation code for reproducing our camera pose estimation results on Co3D is now available in the evaluation branch." |
| Fine-tuning | The paper says its limitations can be addressed "by fine-tuning the model on targeted datasets with minimal architectural modifications." |
| Smaller models | The README's checklist shows "Release VGGT-500M and VGGT-200M" as not yet checked off, as read on November 15, 2026. |